Reading & Understanding Data · Lesson 30

Numeric vs Categorical Variables

Numeric vs Categorical Variables is part of data understanding.

ConceptWorked examplePracticeKnowledge check
Textbook walkthrough

What Numeric vs Categorical Variables actually means

Numeric vs Categorical Variables is part of data understanding. Before analysis, you need to know what one row represents, what each field means, how values are encoded and which operations are valid for each variable type.

Numeric vs Categorical Variables matters because interpretation begins with understanding what each row and field actually represents. File syntax, software dtype and business meaning are different layers; confusing them leads to invalid summaries and comparisons.

Deeper walkthrough

Read Numeric vs Categorical Variables as a mechanism, not a recipe

Treat this as a sequence of observable decisions rather than one opaque command. Stage 1: Identify the observational unit represented by each row. Stage 2: Inspect column names, dtypes, ranges, categories and missing values. Stage 3: Distinguish identifiers from quantities; numeric storage does not automatically make a variable quantitative. Final checkpoint: Check whether dates/times have time zones and whether text fields contain hidden variants.

Mechanism

Follow the transformation

Identify the observational unit represented by each row.

Inspect column names, dtypes, ranges, categories and missing values.

Distinguish identifiers from quantities; numeric storage does not automatically make a variable quantitative.

Evidence

Know what would convince you

  • Compare row/column counts, dtypes and missing values before and after the operation.
  • Trace a few representative rows or one group manually from source values to result.
Useful distinctionNominal: Categories with no intrinsic order, e.g. region.
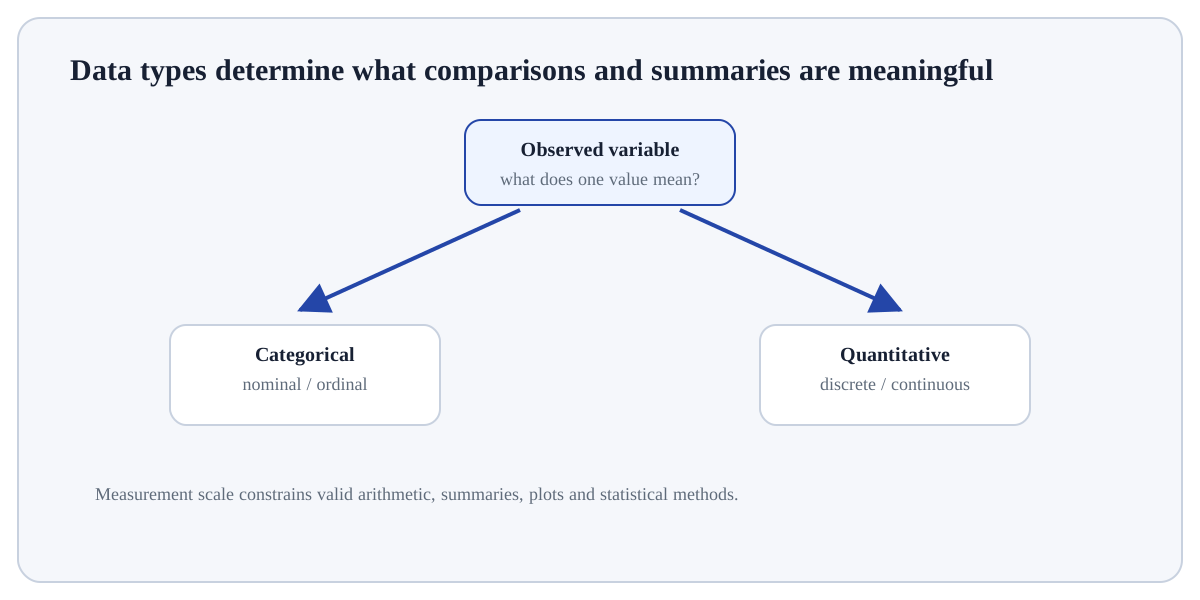
Visual demonstration of Numeric vs Categorical Variables
Visual demonstration: use the diagram to trace the main objects and state changes involved in Numeric vs Categorical Variables.
How it works

Trace the mechanism step by step

  1. Identify the observational unit represented by each row.
  2. Inspect column names, dtypes, ranges, categories and missing values.
  3. Distinguish identifiers from quantities; numeric storage does not automatically make a variable quantitative.
  4. Document units, category definitions and permissible values.
  5. Check whether dates/times have time zones and whether text fields contain hidden variants.
Worked demonstration

Make the concept concrete

Demonstration

Python / pandas example

# Step 1 — Import the module so its functions/classes are available to the rest of this example.
import pandas as pd
# Step 2 — Construct `df` as a tabular object with named columns for inspectable analysis.
df = pd.DataFrame({
  "customer_id":[101,102,103],
  "segment":["A","B","A"],
  "age":[34,29,41],
  "signup":["2026-01-02","2026-02-15","2026-03-01"]
})
# Step 3 — Execute this statement and inspect how it changes the current value, object or program state.
df["signup"] = pd.to_datetime(df["signup"])
# Step 4 — Display the current value explicitly so the result/state can be inspected during execution.
print(df.dtypes)
Expected / illustrative result
customer_id is stored numerically but is an identifier; segment is categorical; age is quantitative; signup becomes datetime. Storage dtype and statistical role are related but not identical.
Interpret the result.

For Numeric vs Categorical Variables, trace representative source rows/columns into the result and reconcile row counts, dtypes, keys or missing values that the operation could change.

Distinctions & related ideas

Know what this is — and what it is not

NominalCategories with no intrinsic order, e.g. region.
OrdinalOrdered categories where gaps are not assumed equal, e.g. satisfaction levels.
IntervalEqual differences are meaningful but zero is arbitrary, e.g. Celsius temperature.
RatioEqual differences plus a meaningful zero, e.g. mass or duration.
Discrete / continuousCounts take separated values; measured quantities can vary over a continuum.
Use deliberately

When it is appropriate

Use Numeric vs Categorical Variables when the data are naturally tabular and row grain, column meaning, keys and dtypes can be stated explicitly.

Boundary conditions

When to stop or reconsider

Reconsider the operation if row identity/grain is unclear, join keys are not validated, chained transformations hide state, or the task is better expressed with a simpler table operation.

Common mistakes

Failure modes to recognise

  • Changing row grain or row count without noticing it.
  • Joining/grouping on keys whose uniqueness or missingness was never checked.
  • Interpreting a derived column or aggregation without reconciling it to source rows and units.
Verification

How to check the result

  • Compare row/column counts, dtypes and missing values before and after the operation.
  • Trace a few representative rows or one group manually from source values to result.
  • For joins/reshapes/grouping, verify key uniqueness/cardinality and reconcile totals where totals should be preserved.
Hands-on practice

Demonstrate understanding

Try this:

Build a tiny, inspectable example of Numeric vs Categorical Variables. First identify the observational unit represented by each row. Then inspect column names, dtypes, ranges, categories and missing values. Write the expected result before running it, and explain one condition that would make the result misleading or invalid.

Work with 4–8 rows that contain the exact key/category/missing-value pattern you want to understand. Trace one row or group all the way through.
Knowledge check

Check reasoning, not memorisation

Before trusting a result from Numeric vs Categorical Variables, which check provides the strongest evidence that you understand and applied it correctly?

Quick reference

Keep the important distinctions visible

Step 1Identify the observational unit represented by each row.
Step 2Inspect column names, dtypes, ranges, categories and missing values.
Step 3Distinguish identifiers from quantities; numeric storage does not automatically make a variable quantitative.
Step 4Document units, category definitions and permissible values.
Lesson summary

What to remember

  • Numeric vs Categorical Variables is part of data understanding. Before analysis, you need to know what one row represents, what each field means, how values are encoded and which operations are valid for each variable type.
  • Identify the observational unit represented by each row.
  • Changing row grain or row count without noticing it.
  • Compare row/column counts, dtypes and missing values before and after the operation.