
Follow the transformation
Define the prediction unit and what “new” means: new row, subject, group or future time.
Reserve test data for final evaluation when feasible.
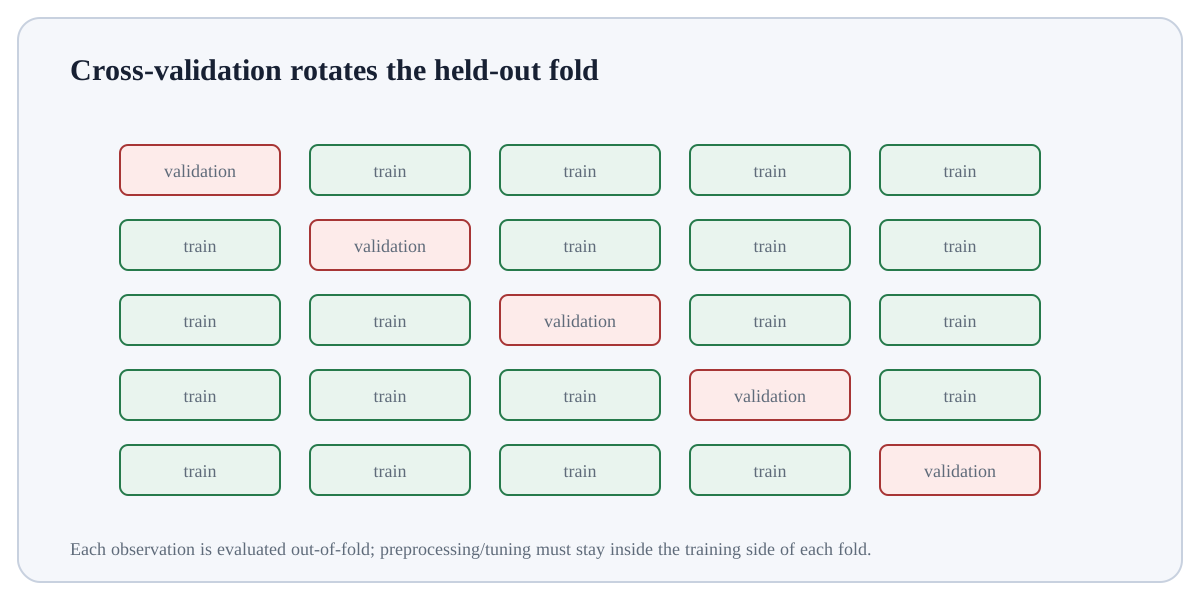
Use cross-validation inside development to compare models/hyperparameters.
Group K Fold is a model-validation design.
Group K Fold is a model-validation design. Validation estimates how a trained procedure will generalise to new cases, so the split must reproduce the independence structure and time/entity boundaries expected at deployment.
Group K Fold matters because validation estimates future performance only when held-out examples are genuinely independent under the deployment scenario. Random, stratified, grouped and temporal splits answer different generalisation questions.
Treat this as a sequence of observable decisions rather than one opaque command. Stage 1: Define the prediction unit and what “new” means: new row, subject, group or future time. Stage 2: Reserve test data for final evaluation when feasible. Stage 3: Use cross-validation inside development to compare models/hyperparameters. Final checkpoint: Use group- or time-aware splits when ordinary random splitting would leak related/future information.
Define the prediction unit and what “new” means: new row, subject, group or future time.
Reserve test data for final evaluation when feasible.
Use cross-validation inside development to compare models/hyperparameters.
# Step 1 — Import only the named objects needed by the following steps, keeping dependencies explicit.
from sklearn.model_selection import GroupKFold
# Step 2 — Compute the right-hand expression and store its result in `X` for the next step.
X = [[0],[1],[2],[3],[4],[5]]
# Step 3 — Compute the right-hand expression and store its result in `groups` for the next step.
groups = [1,1,2,2,3,3]
# Step 4 — Iterate through the collection so the indented block is applied once for each item.
for tr,va in GroupKFold(3).split(X, groups=groups):
    # Step 5 — Display the current value explicitly so the result/state can be inspected during execution.
print("train groups", {groups[i] for i in tr}, "valid groups", {groups[i] for i in va})Each group appears entirely in train or validation for a fold; no entity is split across them.
For Group K Fold, connect the reported result to the exact training/validation/prediction step that produced it and check one prediction, fold or metric component independently.
HoldoutOne train/test split; simple but higher variance.K-foldEach fold serves once as validation; assumes rows are exchangeable.StratifiedPreserves class proportions approximately.Group K-foldKeeps all rows from the same group together.Time-series splitTrains on past and validates on later data.Nested CVOuter loop estimates generalisation; inner loop selects/tunes.Use Group K Fold when it reflects how genuinely unseen cases will arrive and keeps every learned choice inside the training portion of each evaluation split.
Choose a different split strategy when observations share subjects/groups, have temporal order, or otherwise violate independent random splitting assumptions.
Build a tiny, inspectable example of Group K Fold. First define the prediction unit and what “new” means: new row, subject, group or future time. Then reserve test data for final evaluation when feasible. Write the expected result before running it, and explain one condition that would make the result misleading or invalid.
Before trusting a result from Group K Fold, which check provides the strongest evidence that you understand and applied it correctly?
Step 1Define the prediction unit and what “new” means: new row, subject, group or future time.Step 2Reserve test data for final evaluation when feasible.Step 3Use cross-validation inside development to compare models/hyperparameters.Step 4Keep all preprocessing, feature selection and tuning inside each training fold.