Metrics encode which mistakes matter. Accuracy treats all correct decisions equally; precision, recall, F1, ROC-AUC, PR-AUC and log loss answer different questions.
Building interactive view…
Understand
Build the mental model
Metrics encode which mistakes matter. Accuracy treats all correct decisions equally; precision, recall, F1, ROC-AUC, PR-AUC and log loss answer different questions. Start from decision costs and class prevalence. For rare positives, PR curves and precision/recall are often more informative than accuracy.
What happens if…?
Break the assumption deliberately
Make positives rare while keeping accuracy high and inspect what the confusion matrix reveals.
Move the control and explain what you expect before reading the visual.
Technical lens
Formalise what the visual is doing
Confusion-matrix counts produce threshold-dependent metrics. Ranking metrics evaluate score ordering; probabilistic metrics evaluate probability quality.
Technical questionUse a tiny case to make the mechanism observable. Confusion-matrix counts produce threshold-dependent metrics. Ranking metrics evaluate score ordering; probabilistic metrics evaluate probability quality. Verify one intermediate quantity, state change or mapping independently; then predict the consequence of this change: Make positives rare while keeping accuracy high and inspect what the confusion matrix reveals.
Practitioner lens
Use it responsibly
Start from decision costs and class prevalence. For rare positives, PR curves and precision/recall are often more informative than accuracy.
Transfer testTransfer this idea to a new example and justify each decision using this practitioner rule: Start from decision costs and class prevalence. For rare positives, PR curves and precision/recall are often more informative than accuracy. Then explain what should change if you deliberately test: Make positives rare while keeping accuracy high and inspect what the confusion matrix reveals.
Worked exploration
Use the visual as an experiment, not decoration
For TP=30, FP=10, FN=20, TN=40, compute accuracy, precision and recall. Change the decision threshold so fewer cases are predicted positive and watch precision/recall move in opposite directions.
Technical lens
Confusion-matrix counts produce threshold-dependent metrics. Ranking metrics evaluate score ordering; probabilistic metrics evaluate probability quality.
Practitioner check
Start from decision costs and class prevalence. For rare positives, PR curves and precision/recall are often more informative than accuracy.
Prediction before interaction
Make positives rare while keeping accuracy high and inspect what the confusion matrix reveals.
Exploration walkthrough
Turn the interaction into an evidence trail
For TP=30, FP=10, FN=20, TN=40, compute accuracy, precision and recall. Change the decision threshold so fewer cases are predicted positive and watch precision/recall move in opposite directions. Before moving the control, state your prediction. After the visual changes, name the specific state, statistic, boundary or mapping that changed and explain why that change is consistent—or inconsistent—with your prediction.
Record one observable quantity before the interaction and the same quantity afterwards.
Change one factor at a time so the causal effect of the control is inspectable.
Use an edge or failure case to discover where the concept stops behaving as the simple story suggests.
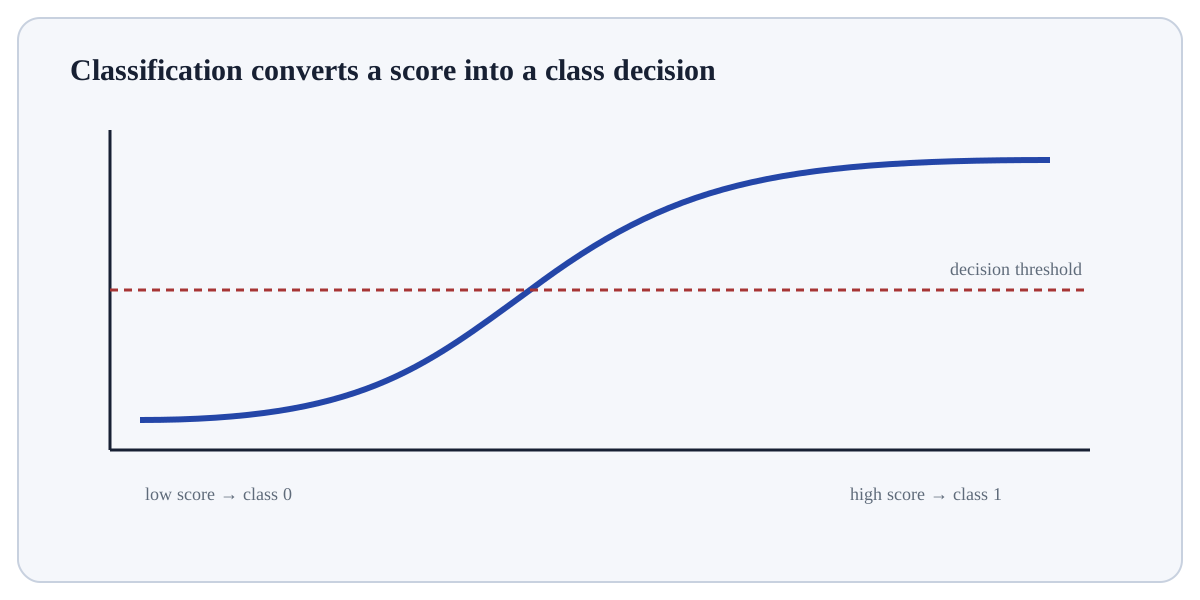
Static orientation diagram for Classification Metrics; use the interactive visual above to test how the relationships change.
Reference depth
Open the complete material
The flagship experience is the map. These pages contain the roads.