
Follow the transformation
Generate predictions on held-out data.
For probabilistic classifiers, separate probability quality from thresholded decisions.
Compute metrics with the positive class and averaging convention explicitly defined.
PR AUC evaluates a particular aspect of prediction quality.
PR AUC evaluates a particular aspect of prediction quality. No single metric captures discrimination, calibration, threshold costs and subgroup performance simultaneously; choose metrics based on the decision and class/base-rate structure.
PR AUC matters because classification and regression metrics answer different operational questions. Ranking, probability quality, threshold decisions and error magnitudes should be evaluated separately when the application cares about them separately.
Treat this as a sequence of observable decisions rather than one opaque command. Stage 1: Generate predictions on held-out data. Stage 2: For probabilistic classifiers, separate probability quality from thresholded decisions. Stage 3: Compute metrics with the positive class and averaging convention explicitly defined. Final checkpoint: Choose an operating threshold using validation data and decision costs, then freeze it for test evaluation.
Generate predictions on held-out data.
For probabilistic classifiers, separate probability quality from thresholded decisions.
Compute metrics with the positive class and averaging convention explicitly defined.
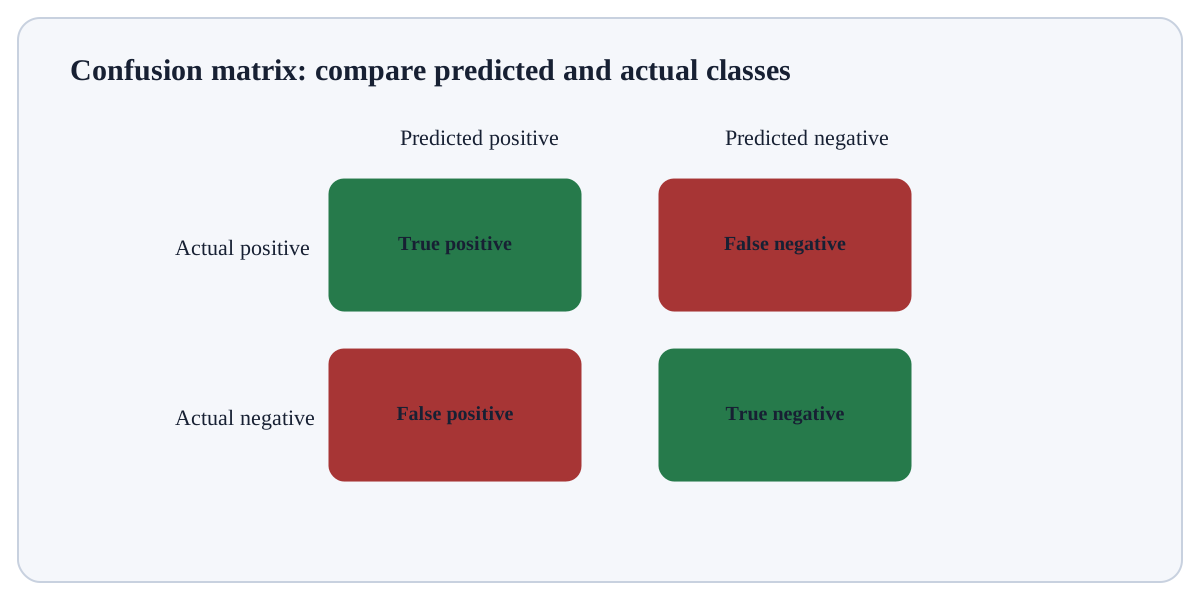
Generate predictions on held-out data. Treat the output from PR AUC as evidence to inspect: confirm its type, shape, range or units and connect it back to the input that produced it.
At stricter thresholds: precision often rises while recall falls.
At looser thresholds: recall rises while precision may fall.
PR curves focus on positive predictions and are strongly affected by prevalence.Use the curve to select an operating region on validation data; evaluate the frozen threshold on held-out test data.
For PR AUC, connect the reported result to the exact training/validation/prediction step that produced it and check one prediction, fold or metric component independently.
PrecisionTP/(TP+FP): reliability of positive predictions.RecallTP/(TP+FN): detection of actual positives.F1/FβHarmonic combination of precision/recall; β weights recall relative to precision.ROC-AUCProbability a random positive ranks above a random negative.PR-AUCPrecision-recall ranking summary, sensitive to prevalence.Brier/log lossProbability-quality scores that penalise miscalibrated/confident errors.Use PR AUC when the metric/diagnostic corresponds to the prediction type, positive class or business/scientific consequence that matters.
Do not compress performance to this measure alone when thresholds, class imbalance, calibration, subgroup behaviour or error costs change the decision.
For strongly imbalanced targets, ROC-AUC and PR-AUC answer different ranking questions. A feature-level AUC screen should be interpreted alongside class prevalence and validated in the final multivariate pipeline.
Build a tiny, inspectable example of PR AUC. First generate predictions on held-out data. Then for probabilistic classifiers, separate probability quality from thresholded decisions. Write the expected result before running it, and explain one condition that would make the result misleading or invalid.
Before trusting a result from PR AUC, which check provides the strongest evidence that you understand and applied it correctly?
Step 1Generate predictions on held-out data.Step 2For probabilistic classifiers, separate probability quality from thresholded decisions.Step 3Compute metrics with the positive class and averaging convention explicitly defined.Step 4Inspect a curve/confusion matrix/residual distribution in addition to scalar metrics.